
Step 1. Building a database
NoteTerminology differences:
- On this page and in the LexicMap command line options, the term “mask” is used, following the terminology in the LexicHash paper.
- In the LexicMap manuscript, however, we use “probe” as it is easier to understand. These masks consist of thousands of k-mers and capture k-mers from sequences through prefix matching, functioning similarly to DNA probes in molecular biology.
- Prepare input files:
- Sequences of each reference genome should be saved in a separate FASTA file, with identifiers (no tab symbols) in the file names.
E.g., GCF_000006945.2.fna.gz
- A regular expression is also available to extract the reference ID from the file name.
E.g.,
--ref-name-regexp '^(\w{3}_\d{9}\.\d+)'extractsGCF_000006945.2from GenBank assembly fileGCF_000006945.2_ASM694v2_genomic.fna.gz. - Even if you forgot to use
-N/--ref-name-regexp, lexicmap utils edit-genome-ids (available since v0.8.0) can fix this without rebuilding the index.
- A regular expression is also available to extract the reference ID from the file name.
E.g.,
- If you save a few small (viral) complete genomes (one sequence per genome) in each file, it’s feasible as sequence IDs in search results can help distinguish target genomes.
- Sequences of each reference genome should be saved in a separate FASTA file, with identifiers (no tab symbols) in the file names.
E.g., GCF_000006945.2.fna.gz
- Run:
-
From a directory with multiple genome files:
lexicmap index -I genomes/ -O db.lmi -
From a file list with one file per line:
lexicmap index --skip-file-check -X files.txt -O db.lmi
-
NoteGenome size
LexicMap is mainly suitable for small genomes like Archaea, Bacteria, Viruses, fungi, and plasmids.Maximum genome size: 268 Mb (268,435,456). More precisely:
$total_bases + ($num_contigs - 1) * 1000 <= 268,435,456as we concatenate contigs with 1000-bp intervals of N’s to reduce the number of sequences to index.
Sequences of each reference genome should be saved in a separate FASTA file, with identifiers in the file names. If you save a few small (viral) complete genomes (one sequence per genome) in each file, it’s feasible as sequence IDs in search results can help distinguish target genomes.
- File type: FASTA/Q files, in plain text or gzip/xz/zstd/bzip2/lz4 compressed formats.
- File name: “Genome ID” + “File extension”. E.g.,
GCF_000006945.2.fna.gz.- Genome ID: IDs must not contain tab ("\t") symbols and should be distinct for accurate interpretation of results. They will be shown in the search results.
- A regular expression is also available to extract the reference ID from the file name.
E.g.,
--ref-name-regexp '^(\w{3}_\d{9}\.\d+)'extractsGCF_000006945.2from GenBank assembly fileGCF_000006945.2_ASM694v2_genomic.fna.gz. - If you forgot to use
-N/--ref-name-regexp, lexicmap utils edit-genome-ids (available since v0.8.0) can fix this without rebuilding the index.
- A regular expression is also available to extract the reference ID from the file name.
E.g.,
- Genome ID: IDs must not contain tab ("\t") symbols and should be distinct for accurate interpretation of results. They will be shown in the search results.
- File extension: a regular expression set by the flag
-r/--file-regexpis used to match input files. The default value supports common sequence file extensions, e.g.,.fa,.fasta,.fna,.fa.gz,.fasta.gz,.fna.gz,fasta.xz,fasta.zst, andfasta.bz2. - Sequences:
- Only DNA or RNA sequences are supported.
- Soft-masked sequences have been supported since v0.9.0 with the flag
--soft-masking. Lowercase bases in soft-masked low-complexity regions will be treated as A’s and won’t be seeded, while they will be saved for base-level alignment.
- Soft-masked sequences have been supported since v0.9.0 with the flag
- Sequence IDs should be distinct for accurate interpretation of results. They will be shown in the search results.
- Sequence descriptions (text after the sequence ID) are not saved. If you do need them, you can create a mapping file
(
cat files.txt | seqkit seq -n -X - | sed -E 's/\s+/\t/' > id2desc.tsv) and use it to add descriptions to search results. - One or more sequences (contigs) in each file are allowed.
- Unwanted sequences (such as plasmids) can be filtered out by regular expressions from the flag
-B/--seq-name-filter.
- Unwanted sequences (such as plasmids) can be filtered out by regular expressions from the flag
- Genome size limit. Some non-isolate assemblies might have extremely large genomes, e.g., GCA_000765055.1 has >150 Mb.
The flag
-g/--max-genome(default 20 Mb) is used to skip these input files, and the file list would be written to a file via the flag-G/--big-genomes.- Changes since v0.5.0:
- Genomes with any single contig larger than the threshold will be skipped as before.
- However, fragmented (with many contigs) genomes with a total number of bases larger than the threshold will
be split into chunks and alignments from these chunks will be merged in
lexicmap search.
- For fungal genomes, please increase the value of
-g/--max-genome.
- Changes since v0.5.0:
- Minimum sequence length. A flag
-l/--min-seq-lencan filter out sequences shorter than the threshold (default is thekvalue).
- Only DNA or RNA sequences are supported.
- At most 17,179,869,184 (234) genomes are supported. For more genomes, please create a file list and split it into multiple parts, and build an index for each part.
Input files can be given in one of the following ways:
- Positional arguments. For a few input files.
- A file list via the flag
-X/--infile-listwith one file per line. It can be STDIN (-), e.g., you can filter a file list and pass it tolexicmap index.- The flag
-S/--skip-file-checkis optional and skips input file checks if you are sure these files exist. By default, LexicMap checks the existence of all input files, which would take tens of minutes for >1M files.
- The flag
- A directory containing input files via the flag
-I/--in-dir.- Multiple-level directories are supported. So you don’t need to save hundreds of thousands of files in one directory.
- Directory and file symlinks are followed.
See benchmark of index building.
LexicMap is designed to provide fast and low-memory sequence alignment against millions of prokaryotic genomes.
- CPU:
- No specific requirements on CPU type and instruction sets. Both x86 and ARM chips are supported.
- More is better as LexicMap is CPU-intensive software. It uses all CPUs by default (
-j/--threads).
- RAM
- Examples (v0.10.0):
- 0.2 million GTDB r232 representative prokaryotic genomes (-b 5000): 78 G.
- 2.3 million GenBank+Refseq prokaryotic genomes (-b 25000): 134 GB.
- 2.3 million AllTheBacteria bacterial genomes (-b 25000): 117 GB.
- More RAM (> 200 GB for >2 million genomes) is preferred. The memory usage in index building is mainly related to:
- The number of masks (
-m/--masks, default 20,000). Bigger values improve the search sensitivity slightly, increase the index size, and slow down the search speed. For smaller genomes like phages/viruses, m=5,000 is high enough. - The number of genomes. Generally, more genomes consume more memory, but we can reduce it by using smaller genome batch sizes (see below).
- The genome batch size (
-b/--batch-size, default 5,000). This is the main parameter to adjust memory usage. Bigger values increase indexing memory usage. - The divergence between genome sequences in each batch. Diverse genomes consume more memory.
- The maximum seed distance or the maximum sketching desert size (
-D/--seed-max-desert, default 100), and the distance of k-mers to fill deserts (-d/--seed-in-desert-dist, default 50). These are the main parameters to adjust search sensitivity. Bigger-D/--seed-max-desertvalues decrease the search sensitivity, speed up indexing, decrease indexing memory usage, and decrease index size. Alignment speed is largely unaffected.
- The number of masks (
- If the RAM is not sufficient. Please:
- Use a smaller genome batch size. It decreases indexing memory usage and has little effect on search performance.
- Examples (v0.10.0):
- Disk
- More is better. LexicMap index size is related to the number of input genomes, the divergence between genome sequences, the number of masks, and the maximum seed distance. See some examples.
- Note that index size grows sublinearly with the number of genomes. Because seed data are compressed with the VARINT-GB algorithm, more genomes lead to smaller compression ratios.
- SSD disks are preferred, while HDD disks are also fast enough.
- More is better. LexicMap index size is related to the number of input genomes, the divergence between genome sequences, the number of masks, and the maximum seed distance. See some examples.
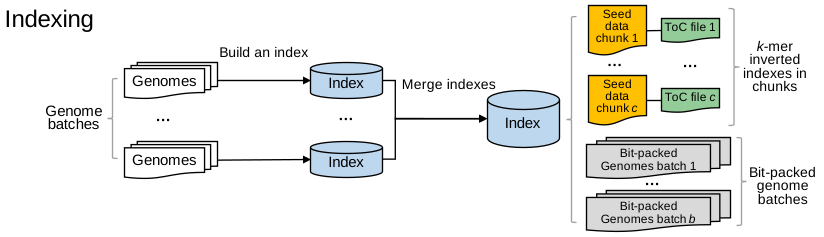
See the paper for details.
NoteQuery length
LexicMap is mainly designed for sequence alignment with a small number of queries (gene/plasmid/virus/phage sequences) longer than 150 bp by default.
If you want to search some short reads, you need to build the index with small values of
-D/--seed-max-desert(default 100) and-d/--seed-in-desert-dist(default 50), e.g.,-D 60 -d 30for 125bp reads, or-D 50 -D 25for 100bp reads. This will increase indexing time and index size. This is less of a concern with a small number of genomes, such as < 10,000.If you just want to search long (>1kb) queries for highly similar (>95%) targets, you can build an index with a bigger
-D/--seed-max-desert(default 100) and-d/--seed-in-desert-dist(default 50), e.g.,-D 300 -d 150. Bigger values decrease search sensitivity for distant targets, speed up indexing, decrease indexing memory usage, and decrease index size. Alignment speed is largely unaffected.Note that LexicMap is slow for ultra-long (>1Mb) queries, and the alignment might be fragmented.
Flags in bold text are important and frequently used.
| Flag | Value | Function | Comment |
|---|---|---|---|
-j/--threads |
Default: all available CPUs | Number of CPU cores to use. | ► If the value is smaller than the number of available CPUs, make sure to use the same value for -c/--chunks. |
--soft-masking |
Default: false | Support soft-masked sequences | ► Lowercase bases in soft-masked low-complexity regions will be treated as A’s and won’t be seeded, while they will be saved for base-level alignment. |
| Flag | Value | Function | Comment |
|---|---|---|---|
-b/--batch-size |
Max: 131072, default: 5000 | Maximum number of genomes in each batch | If the number of input files exceeds this number, input files are split into multiple batches and indexes are built for all batches. In the end, seed files are merged, while genome data files are kept unchanged and collected. ■ Bigger values increase indexing memory usage and increase batch searching speed, while single-query search speed is not affected. |
| Flag | Value | Function | Comment |
|---|---|---|---|
-M/--mask-file |
A file | File with custom masks | File with custom masks, which can be exported from an existing index or newly generated by “lexicmap utils masks”. This flag overrides -k/--kmer, -m/--masks, -s/--rand-seed, etc. |
-k/--kmer |
Max: 32, default: 31 | K-mer size | ■ Bigger values improve the search specificity and do not increase the index size. |
-m/--masks |
Default: 20,000 | Number of masks | ■ Bigger values improve the search sensitivity slightly, increase the index size, and slow down the search speed. For smaller genomes like phages/viruses, m=5,000 is high enough. |
| Flag | Value | Function | Comment |
|---|---|---|---|
--seed-max-desert |
Default: 100 | Maximum length of distances between seeds | The default value of 100 guarantees that queries >=200 bp will match at least two seeds. ► Large regions with no seeds are called sketching deserts. Deserts with seed distance larger than this value will be filled by choosing k-mers roughly every –seed-in-desert-dist (50 by default) bases. ■ Bigger values decrease the search sensitivity for distant targets, speed up indexing, decrease indexing memory usage, and decrease index size. Alignment speed is largely unaffected. |
-c/--chunks |
Maximum: 128, default: value of -j/–threads | Number of seed file chunks | Bigger values accelerate the search speed at the cost of a higher disk read load. ► The value should not exceed the maximum number of open files set by the operating system. ► Make sure the value of -j/--threads in lexicmap search is >= this value. |
-J/--seed-data-threads |
Maximum: -c/–chunks, default: 8 | Number of threads for merging seed chunks from all batches | Merging reserves 9 open files. The actual number of merging threads is min(–seed-data-threads, (–max-open-files - 9)/($inputs + $outputs)), where $inputs is the current group size and $outputs is 2, or 3 for the final merge with --seed-index2. ■ Bigger values increase I/O load in HDDs for large batch counts. |
--partitions |
Default: 4096 | Number of partitions for indexing each seed file | Bigger values slightly increase memory usage. ► After indexing, lexicmap utils reindex-seeds can be used to reindex the seed data with another value of this flag. |
-2/--seed-index2 |
Default: false | Create adaptive two-level seed indexes | Recommended. Speeds up prefix matching in large indexes by using longer prefixes to locate seeds within large data blocks. Overall gains are most noticeable for batch queries with lexicmap search when -n/--top-n-genomes limits downstream alignments, making seed matching a larger share of runtime. Without this limit, sequence alignment often dominates runtime. Writes both indexes alongside the final seeds. Produces the same indexes as lexicmap utils reindex-seeds2. Uses --partitions (power of 4, at least 4); K minus the primary prefix length must be in [2, 20]. |
--seed-index2-threshold |
Default: 8K, minimum: 4K | Minimum seed block size for a secondary index | Used with --seed-index2; equivalent to reindex-seeds2 --threshold. The additional .idx15 files are typically similar in size to the .idx files, and often smaller. Higher values reduce .idx15 size but limit the speedup. The default 8K is recommended. |
--max-open-files |
Default: 1024 | Maximum number of open files | Limits file parsing, seed writing, and batch merging, including 9 reserved descriptors (minimum: 13; 14 with --save-seed-pos or multi-batch --seed-index2). Large batch counts are merged in multiple rounds. Increasing the budget can allow more merging threads; set ulimit -n at least this high. |
Also see the usage of lexicmap index.
If you have hundreds of thousands of input genomes or more, it’s better to control the number of genome batches, which can be calculated via
$num_input_files / --batch-size
E.g., for GenBank prokaryotic genomes: 2,340,672 / 5000 (default) = 468.
The number is too big, and it would slow down the seed-data merging step in lexicmap index and candidate sequence extraction in lexicmap search.
Therefore, if you have enough memory, you can set a bigger --batch-size (e.g., 2,340,672 / 25000 = 93.6).
If the batch number is still big (e.g. 300), you can set bigger --max-open-files (e.g., 4096) and -J/--seed-data-threads (e.g., 12. 12 <= (4096-9)/(300+2) = 13.5)
to accelerate the merging step. Meanwhile, don’t forget to increase the maximum open files per process via ulimit -n 4096.
If you forgot these settings, you can rerun the merging step for an unfinished index via lexicmap utils remerge (available since v0.5.0, also see FAQ: how to resume the indexing). Other cases to use this command:
- Only one thread is used for merging indexes, which happens when there are
many batches (>200) (
$inpu_files / --batch-size) and the value of--max-open-filesis not large enough. - The Slurm/PBS job time limit is almost reached and the merging step won’t finish in time.
- The disk quota is reached during the merging step.
We use a small dataset for demonstration.
-
Preparing the test genomes (15 bacterial genomes) in the
refsdirectory.Note that the genome files contain the assembly accessions (ID) in the file names.
git clone https://github.com/shenwei356/LexicMap cd LexicMap/demo/ ls refs/ GCF_000006945.2.fa.gz GCF_000392875.1.fa.gz GCF_001096185.1.fa.gz GCF_002949675.1.fa.gz GCF_006742205.1.fa.gz GCF_000017205.1.fa.gz GCF_000742135.1.fa.gz GCF_001457655.1.fa.gz GCF_002950215.1.fa.gz GCF_009759685.1.fa.gz GCF_000148585.2.fa.gz GCF_001027105.1.fa.gz GCF_001544255.1.fa.gz GCF_003697165.2.fa.gz GCF_900638025.1.fa.gz -
Building an index with genomes from a directory.
lexicmap index -I refs/ -O demo.lmiIt would take about 2 seconds and 1.5 GB RAM on a 16-CPU PC.
Optionally, we can also use a file list as the input.
 $ head -n 3 files.txt
 refs/GCF_000006945.2.fa.gz
 refs/GCF_000017205.1.fa.gz
 refs/GCF_000148585.2.fa.gz

 lexicmap index -S -X files.txt -O demo.lmi
From v0.10.0, it’s recommended to add -2/--seed-index2 to create adaptive two-level seed indexes during database construction.
These indexes speed up prefix matching in large indexes by using longer prefixes to locate seeds within large data blocks.
Overall gains are most noticeable for batch queries with lexicmap search when -n/--top-n-genomes limits downstream alignments,
making seed matching a larger share of runtime. Without this limit, sequence alignment often dominates runtime.
lexicmap index -I genomes/ -O db.lmi --seed-index2
Both index levels are written alongside the final seed files, without rereading them. For multiple batches, only the final merge creates adaptive indexes.
The additional .idx15 files are typically similar in size to the .idx files, and often smaller.
Their size depends mainly on --seed-index2-threshold for lexicmap index or --threshold for lexicmap utils reindex-seeds2.
Higher thresholds reduce .idx15 size but limit the speedup. The default 8K is recommended (minimum: 4K).
For existing databases, use lexicmap utils reindex-seeds2.
Running lexicmap utils reindex-seeds switches back to single-level indexes and removes the corresponding .idx15 files.
The LexicMap index is a directory with multiple files.
$ tree demo.lmi/
demo.lmi/                    # the index directory
├── genomes                  # directory of genome data
│   ├── batch_0000           # genome data of one batch
│   │   ├── genomes.bin      # genome data file, containing genome ID, size, sequence lengths, bit-packed sequences
│   │   └── genomes.bin.idx  # index of genome data file, for fast subsequence extraction
│   └── batch_0001
│   │   ├── genomes.bin
│   │   └── genomes.bin.idx
│   ... ...
├── seeds                    # seed data: pairs of k-mer and its location information (genome batch, genome number, location, strand)
│   ├── chunk_000.bin        # seed data file
│   ├── chunk_000.bin.idx    # index of seed data file, for fast seed searching and data extraction
│   ... ...
│   ├── chunk_015.bin        # the number of chunks is set by flag `-c/--chunks`, default: #cpus
│   └── chunk_015.bin.idx
├── genomes.chunks.bin       # lists of genome chunks which belong to the same genome
├── genomes.map.bin          # mapping genome ID to batch number and genome number in the batch
├── info.toml                # summary of the index
└── masks.bin                # mask data
LexicMap index size is related to the number of input genomes, the divergence between genome sequences, the number of masks, and the maximum seed distance.
Note that index size grows sublinearly with the number of genomes. Because seed data are compressed with the VARINT-GB algorithm, more genomes lead to smaller compression ratios (smaller is better).
# 15 genomes, 54 Mb (54,142,446 bp)

demo.lmi/: 78.36 MiB (82,165,269)
 65.26 MiB      seeds
 12.94 MiB      genomes
156.28 KiB      masks.bin
     600 B      info.toml
     375 B      genomes.map.bin
       0 B      genomes.chunks.bin
# 85,205 genomes, 274 Gbp (273,848,490,566 bp)

gtdb_repr.lmi: 213.27 GiB (228,999,914,466)
146.49 GiB      seeds
 66.78 GiB      genomes
  2.03 MiB      genomes.map.bin
156.28 KiB      masks.bin
     613 B      info.toml
      48 B      genomes.chunks.bin
# 402,538 genomes, 1.5 Tbp (1,501,864,915,560 bp)

gtdb_complete.lmi: 905.34 GiB (972,098,200,328)
542.34 GiB      seeds
362.99 GiB      genomes
  9.60 MiB      genomes.map.bin
156.28 KiB      masks.bin
     616 B      info.toml
     168 B      genomes.chunks.bin
# 2,340,672 genomes, 9.2 Tbp (9,192,651,650,196 bp)

genbank_refseq.lmi: 4.96 TiB (5,454,659,703,138)
  2.79 TiB      seeds
  2.17 TiB      genomes
 55.81 MiB      genomes.map.bin
156.28 KiB      masks.bin
  3.59 KiB      genomes.chunks.bin
     619 B      info.toml
# 1,858,610 genomes, 7.5 Tbp (7,493,622,021,123 bp)

atb_hq.lmi: 3.91 TiB (4,304,515,140,156)
  2.15 TiB      seeds
  1.77 TiB      genomes
 39.22 MiB      genomes.map.bin
156.28 KiB      masks.bin
     619 B      info.toml
      24 B      genomes.chunks.bin
- Directory/file sizes are counted with https://github.com/shenwei356/dirsize v1.2.1 (
dirsize $file, base: 1024). - Index building parameters:
-k 31 -m 20000 -D 100 -d 50. Genome batch size:-b 25000for GenBank+RefSeq and AllTheBacteria datasets,-b 5000(default) for others.
We provide several commands to explore the index data and extract indexed subsequences:
- Extracting sequences
lexicmap utils genome-seqscan extract all sequences of a given genome, see the usage and example.lexicmap utils subseqcan extract subsequences via 1) reference name, sequence ID, position and strand, or 2) search result, see the usage and example.
- Genome data
lexicmap utils genomescan list genome IDs of indexed genomes, see the usage and example.lexicmap utils genome-detailscan extract or view genome details in the index, see the usage and example.
- Seed data
lexicmap utils kmerscan list details of all seeds (k-mers), including reference, location(s), the strand, and the k-mer direction. see the usage and example.lexicmap utils seed-poscan help to explore the seed positions, see the usage and example. Before that, the flag--save-seed-posneeds to be added tolexicmap index.lexicmap utils maskscan list masks of the index, see the usage and example.
Index version information is available in the info.toml file of each LexicMap index.
LexicMap search and other utility commands check compatibility via the main version.
| Index version | LexicMap version | Supported LexicMap versions | Date | Changes |
|---|---|---|---|---|
| 3.5 | 0.10.0 | 0.10.0 + | 2026-10-21 | A small part of seeds are changed after fixing the lexichash computation. |
| 3.4 | 0.7.0 | 0.6.0 + | 2025-04-11 | Fix filling the seed desert region behind the last seed of a genome. |
| 3.3 | 0.6.0 | 0.6.0 + | 2025-03-25 | Reduce index size for batches <= 512. Add the total bases of index to info.toml for computing the Evalue. Denser seeds. |
| 3.1 | 0.5.0 | 0.4.0 + | 2024-12-18 | Change the default partitions of seed data index. |
| 3 | 0.4.0 | 0.4.0 + | 2024-08-15 | Support suffix matching of seeds. Better seed desert filling for highly-repetitive regions. Denser seeds. |
| 1.1 | 0.3.0 | 0.3.0 | 2024-05-14 | Change the format of seed data index. Use longer contig intervals. |
| 0.1 | 0.1.0 | 0.1.0 - 0.2.0 | 2024-01-25 | First version. |
What’s next: